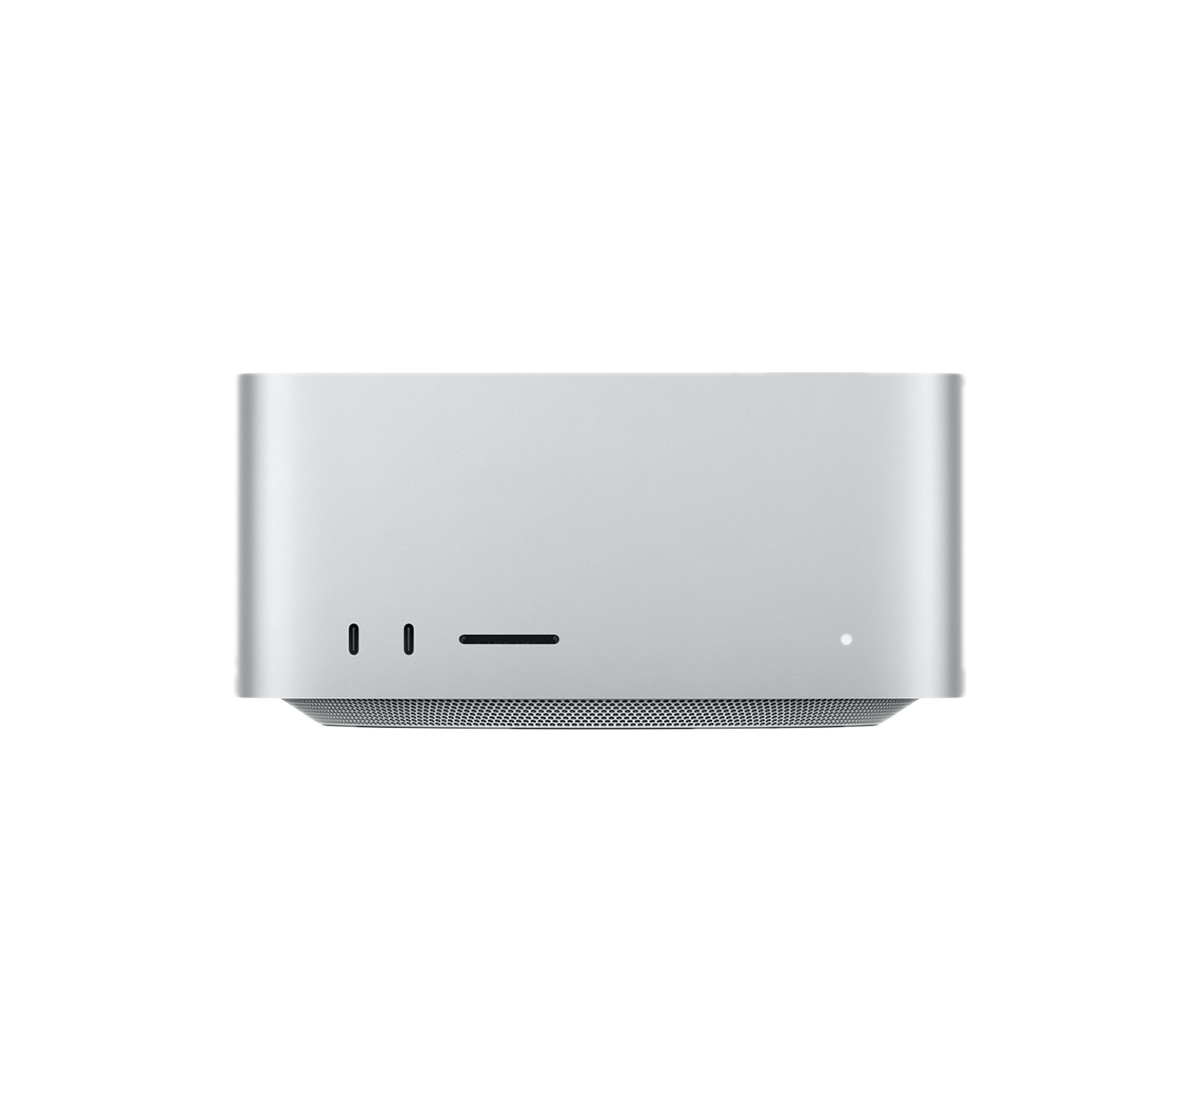
Mac Studio M5 Ultra · 96 GB
1.2 TB/s of unified-memory bandwidth in a near-silent 3.6 kg box — the fastest desk-tier memory in this catalogue, and the M3 Ultra's prompt-speed weakness largely fixed.
Price
£5,499 inc VAT
Apple UK — M5 Ultra 30-core CPU / 64-core GPU, 96 GB / 1 TB · 256 GB +£4,000 (£9,499) · 36C/80C chip +£1,300
verified 2026-11 · supply & lease options in every proposal
 Apple
- 96 GB
- Unified memory
- 1.2 TB/s
- Memory bandwidth
- ~115 tok/s
- gpt-oss-120b
- 385 W
- Max power
256 GB and 512 GB options available
~4.4× a DGX Spark
measured, MLX (M5 Ultra)
Apple-measured, top config · 9 W idle
The M5 Ultra (shipping since 22 September 2026) lifts the Mac Studio's party trick again: 1.2 TB/s to the whole unified pool — about 4.4× a DGX Spark — with Neural Accelerators in every GPU core. Measured on a 256 GB unit, gpt-oss-120b generates at ~115–120 tok/s and Qwen3.5 122B at ~85 tok/s, and dense 70B-class models run at ~23 tok/s.
It also fixes the old weakness: on a 24k-token prompt, prompt processing runs ~3.6× faster than the M3 Ultra (first token in ~6 s rather than ~22 s), so long-document work is now practical. There is still no CUDA — serving is MLX, llama.cpp, LM Studio or Ollama.
The memory options are back after the 2026 shortage: 96 GB from £5,499, 256 GB for £4,000 more, and 512 GB (with the top 36-core/80-core chip) at £22,299 — see the 512 GB entry. Thunderbolt 5 RDMA clustering remains the scale-out path.
vs its siblings: The bandwidth leader of the desk tier — and still the quietest machine in the catalogue.
Memory, to scale
96 GB model-visible · bandwidth is the speed limit
Unified memory
96 GB · 1.2 TB/s
LPDDR5x
For scale
DGX Spark — 128 GB @ 273 GB/s
RTX PRO 6000 — 96 GB @ 1.79 TB/s
DGX Station GB300 — 748 GB coherent
macOS RDMA over Thunderbolt 5 + MLX distributed/exo — Apple quotes up to 3× faster inference from a four-Studio cluster.
What it actually runs
Declared from research and benchmarks, not computed marketing — tokens-per-second figures are cited where a real measurement exists.
- gpt-oss-120bMXFP4with headroom~115–120 tok/s via MLX (M5 Ultra, measured)
- Qwen3.5 122BInt4 (~79 GB)fits~85 tok/s measured — little context headroom at 96 GB
- Mistral Medium 3.5Q4 (~75 GB)fitsdense 128B — ~14 tok/s class at 1.2 TB/s
- Llama-70B-class denseQ4with headroom~23 tok/s (Llama 3.3 70B, measured)
- DeepSeek V4 Flashnative FP4/FP8 (167 GB)2+ units linkedtwo Studios over TB5 RDMA — or order the 256 GB configuration
The full sheet
Compute
- Chip
- Apple M5 Ultra — 30-core CPU (10 super + 20 performance), 64-core GPU base; 36-core CPU / 80-core GPU option (+£1,300)
- Neural Engine
- 32-core · Neural Accelerators in every GPU core
Memory
- Unified memory
- 96 GB @ 1.2 TB/s (256 GB +£4,000 · 512 GB with the 36C/80C chip)
- Model capacity
- ~70 GB usable for weights — 120B-class MoE at 4-bit
Storage & I/O
- SSD
- 1 TB base, to 16 TB
- Networking
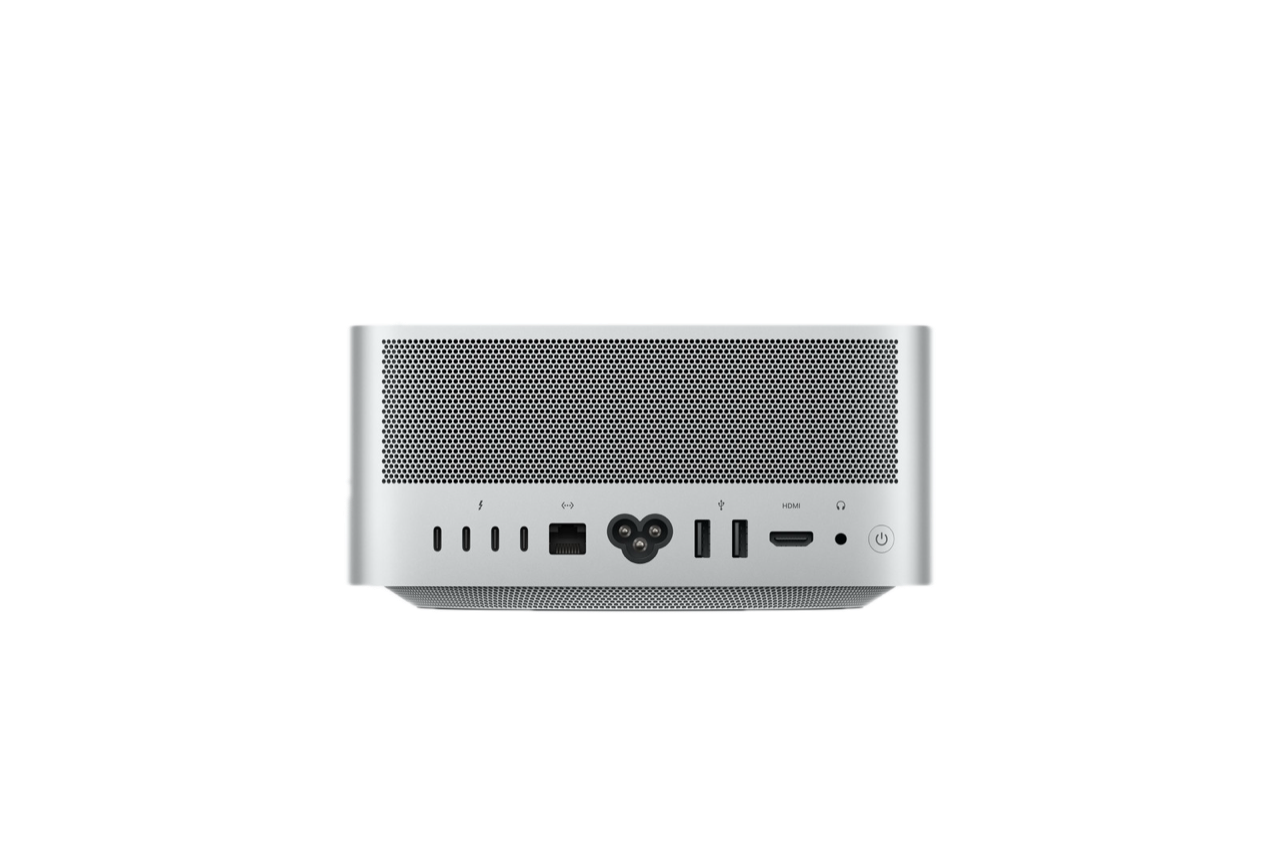
- 10 GbE · Wi-Fi 7
- Ports
- 6× Thunderbolt 5 (2 front, 4 rear) — the clustering fabric
Software
- Serving
- MLX (performance path) · llama.cpp · LM Studio · Ollama
- Note
- No CUDA — vLLM/TensorRT-LLM ecosystems unavailable
Where it shines
- 1.2 TB/s — 120B MoE models at ~115 tok/s, dense 70B at ~23 tok/s
- Prompt processing ~3.6× the M3 Ultra — long documents are now practical
- Near-silent, tiny, 9 W at idle; the easiest machine here to live with
- 256 GB and 512 GB configurations are back — the same box scales up
The trade-offs
- No CUDA: MLX/llama.cpp only, no vLLM-class production serving
- 96 GB caps you at 120B-class models — frontier weights need 256–512 GB
- Memory upgrades are steep: 256 GB adds £4,000, 512 GB means the £22,299 build
Buy this box for
Understanding Apple Mac Studio
Apple M5 Ultra
Apple silicon's unified-memory architecture gives the GPU the entire RAM pool. The M5 Ultra Mac Studio, shipping since 22 September 2026, runs that pool at 1.2 TB/s — about 4.4× a DGX Spark — with Neural Accelerators in every GPU core. Measured on a 256 GB unit, gpt-oss-120b generates at ~115–120 tok/s and dense 70B-class models at ~23 tok/s, and Apple measures the top configuration at 385 W flat out.
The big configurations are back after the 2026 memory shortage withdrew the M3 Ultra's 256 GB and 512 GB options: the M5 Ultra starts at £5,499 with 96 GB, adds 256 GB for £4,000, and offers 512 GB (with the top 36-core CPU / 80-core GPU chip) at £22,299 — orderable since 28 October. There is no 768 GB option. Clustering still works: macOS RDMA over Thunderbolt 5 pools several Studios, and Apple quotes up to 3× faster inference from a four-machine cluster.
Prompt processing, long the platform's weakness, has improved sharply — about 3.6× the M3 Ultra on a 24k-token prompt (Apple claims up to 4×). There is still no CUDA, so you serve through MLX, llama.cpp, LM Studio or Ollama rather than vLLM: the right machine for chat, document and agent workloads, less so for high-concurrency serving.
Sources & verification
Specifications and prices verified 2026-11 against the sources below. The memory shortage is repricing this market monthly — we re-verify at quote.
Compare against the rest of the catalogue, or have us spec it against your workloads.
Back to catalogueSpec the Mac Studio M5 Ultra · 96 GB for your workload
We'll size it against your real token volumes, quote supply and lease options, and stand up the models with evals that prove they do the job — or tell you honestly that a different box (or the API) wins.